

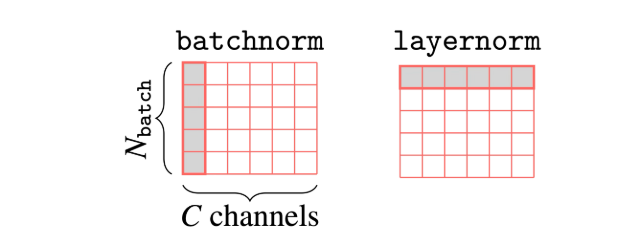
Open In Colab Difference between Batch Normalization and Layer Normalization. LN operates across the feature dimensions for each sample independently, normalizing the activations in a trainable way - effectively its like the transpose of BN Difference between Batch Normalization and Layer Normalization. LN operates across the feature dimensions for each sample independently, normalizing the activations in a trainable way - effectively its like the transpose of BN. We saw that Batch Normalization (BN) is a technique that positions the activations in a trainable way and helps on training efficiency. However, it has some limitations, especially when dealing with small batch sizes. Since it operates across the batch dimension, it normalizes the activations for each feature/channel across the batch. This means that smaller batch sizes can result in inaccurate statistics. This is particularly true in LLMs that are often trained with large models that require small mini-batches due to memory constraints. Therefore in certain architectures such as recurrent networks and transformers, we apply Layer Normalization. The layer normalization of an input vector x∈Rdx \in \mathbb{R}^d is computed as: LayerNorm(x)=γ⊙x−μσ2+ϵ+β\text{LayerNorm}(x) = \gamma \odot \frac{x - \mu}{\sqrt{\sigma^2 + \epsilon}} + \beta where the mean μ\mu and variance σ2\sigma^2 are: μ=1d∑i=1dxi,σ2=1d∑i=1d(xi−μ)2\mu = \frac{1}{d} \sum_{i=1}^{d} x_i, \quad \sigma^2 = \frac{1}{d} \sum_{i=1}^{d} (x_i - \mu)^2 Here:
  • γ\gamma and β\beta are learnable parameters (of shape dd),
  • ϵ\epsilon is a small constant for numerical stability,
  • ⊙\odot denotes element-wise multiplication.
As shown in the figure, it operates across the feature dimensions for each sample independently, normalizing the activations in a trainable way - effectively its like the transpose of BN.

PyTorch reference

Key references: (Bjorck et al., 2018; Santurkar et al., 2018; Zhang & Sennrich, 2019; Ioffe & Szegedy, 2015; Keskar et al., 2016)

References

  • Bjorck, J., Gomes, C., Selman, B., Weinberger, K. (2018). Understanding batch normalization. arXiv [cs.LG].
  • Ioffe, S., Szegedy, C. (2015). Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate Shift. arXiv [cs.LG].
  • Keskar, N., Mudigere, D., Nocedal, J., Smelyanskiy, M., Tang, P. (2016). On Large-Batch Training for Deep Learning: Generalization Gap and Sharp Minima. arXiv [cs.LG].
  • Santurkar, S., Tsipras, D., Ilyas, A., Madry, A. (2018). How does batch Normalization help optimization?. arXiv [stat.ML].
  • Zhang, B., Sennrich, R. (2019). Root mean square layer normalization. arXiv [cs.LG].