- The index runs over the unrolled sequence and the index runs over the cells of the LSTM hidden layer.
- denotes the -th row of the matrix , and denotes the -th element of the vector .
Forward pass
Input gate
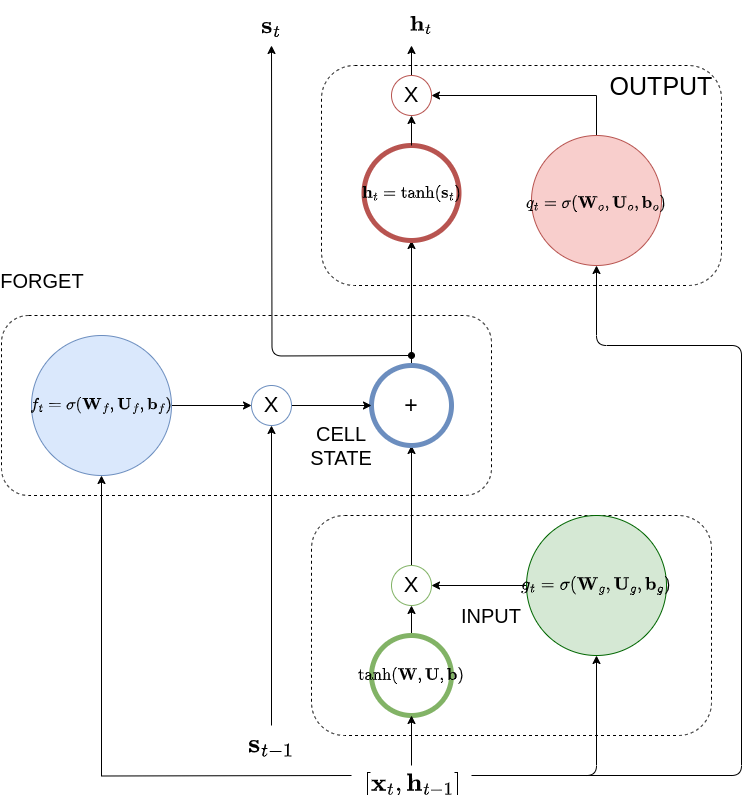
The input gate protects the contents of the cell state from inputs that are irrelevant to the context. The LSTM learns when to let activations from the input layer into the internal state. While the input gate is zero, no activation gets in. The input gate computes the factor The sigmoid produces a factor between 0 and 1 for each cell of the LSTM hidden layer. The factor scales the input of cell . That input combines the previous hidden state, through the dot product , and the current input, through the dot product .Input layer
The input layer is formed exactly like the input of the simple RNN layer in the previous section.Forget gate
The forget gate computes the forgetting factor Like the input gate factor, it lies between 0 and 1. It sets how much of the earlier cell state is preserved.Output gate
The output gate protects the subsequent cells from a hidden state that is irrelevant to their context. The output gate learns when to let the hidden state out.Cell state
The cell state is the core of the LSTM cell. It is the new memory that the LSTM introduces, and the gate factors above exist to preserve it for as long as the task needs it. The update is The parameters are the recurrent weights, the input weights and the bias at the input of the cells.Hidden state
The hidden state is the output of the LSTM cell. It depends on the cell state and the output gate: If the input and output gates are both closed (equal to 0) and the forget gate is fully open (equal to 1), the activation is trapped in the memory cell. It neither grows nor shrinks, and it does not affect the output at intermediate time steps.Output layer
The output layer is the same as in the simple RNN. Depending on the task (classification, regression and so on), it is typically a fully connected layer followed by a softmax or another output unit.Backward pass
Backpropagation works as in the simple RNN, with more complicated expressions. The additive update of the cell state forms what is called the constant error carousel. It lets the gradient flow back across many time steps without exploding or vanishing. In this sense the gates learn when to let the error in and when to let it out. In practice, LSTMs learn long-range dependencies much better than simple RNNs. The time series section that follows trains an LSTM and compares it with simple RNNs on the same data. Greff et al. study the LSTM design and its hyperparameters systematically in “LSTM: A Search Space Odyssey”.Additional resources
These tutorials cover LSTMs from other angles:- A Critical Review of Recurrent Neural Networks for Sequence Learning
- Understanding LSTMs
- Illustrated guide to LSTMs
- Simplest possible LSTM explanation video
PyTorch reference
Key references: (Sak et al., 2014; Collins et al., 2016; Sutskever et al., 2014; Zaremba et al., 2014; Jaderberg et al., 2016)
References
- Collins, J., Sohl-Dickstein, J., Sussillo, D. (2016). Capacity and Trainability in Recurrent Neural Networks. arXiv [stat.ML]. Link
- Jaderberg, M., Czarnecki, W., Osindero, S., Vinyals, O., Graves, A., et al. (2016). Decoupled Neural Interfaces using Synthetic Gradients. arXiv [cs.LG]. Link
- Sak, H., Senior, A., Beaufays, F. (2014). Long Short-Term Memory Based Recurrent Neural Network Architectures for Large Vocabulary Speech Recognition. arXiv [cs.NE]. Link
- Sutskever, I., Vinyals, O., Le, Q. (2014). Sequence to Sequence Learning with Neural Networks. arXiv [cs.CL]. Link
- Zaremba, W., Sutskever, I., Vinyals, O. (2014). Recurrent Neural Network Regularization. arXiv [cs.NE]. Link
Found an error on this page? Report an issue.